Advanced AI & Software Architecture Insights
Architectural blueprints, reproducible benchmarks, and production-ready implementations authored by InexpensiveCoders principal architects and AI researchers.
Subscribe for Zero-Fluff Engineering Whitepapers
 Multi-Agent Systems
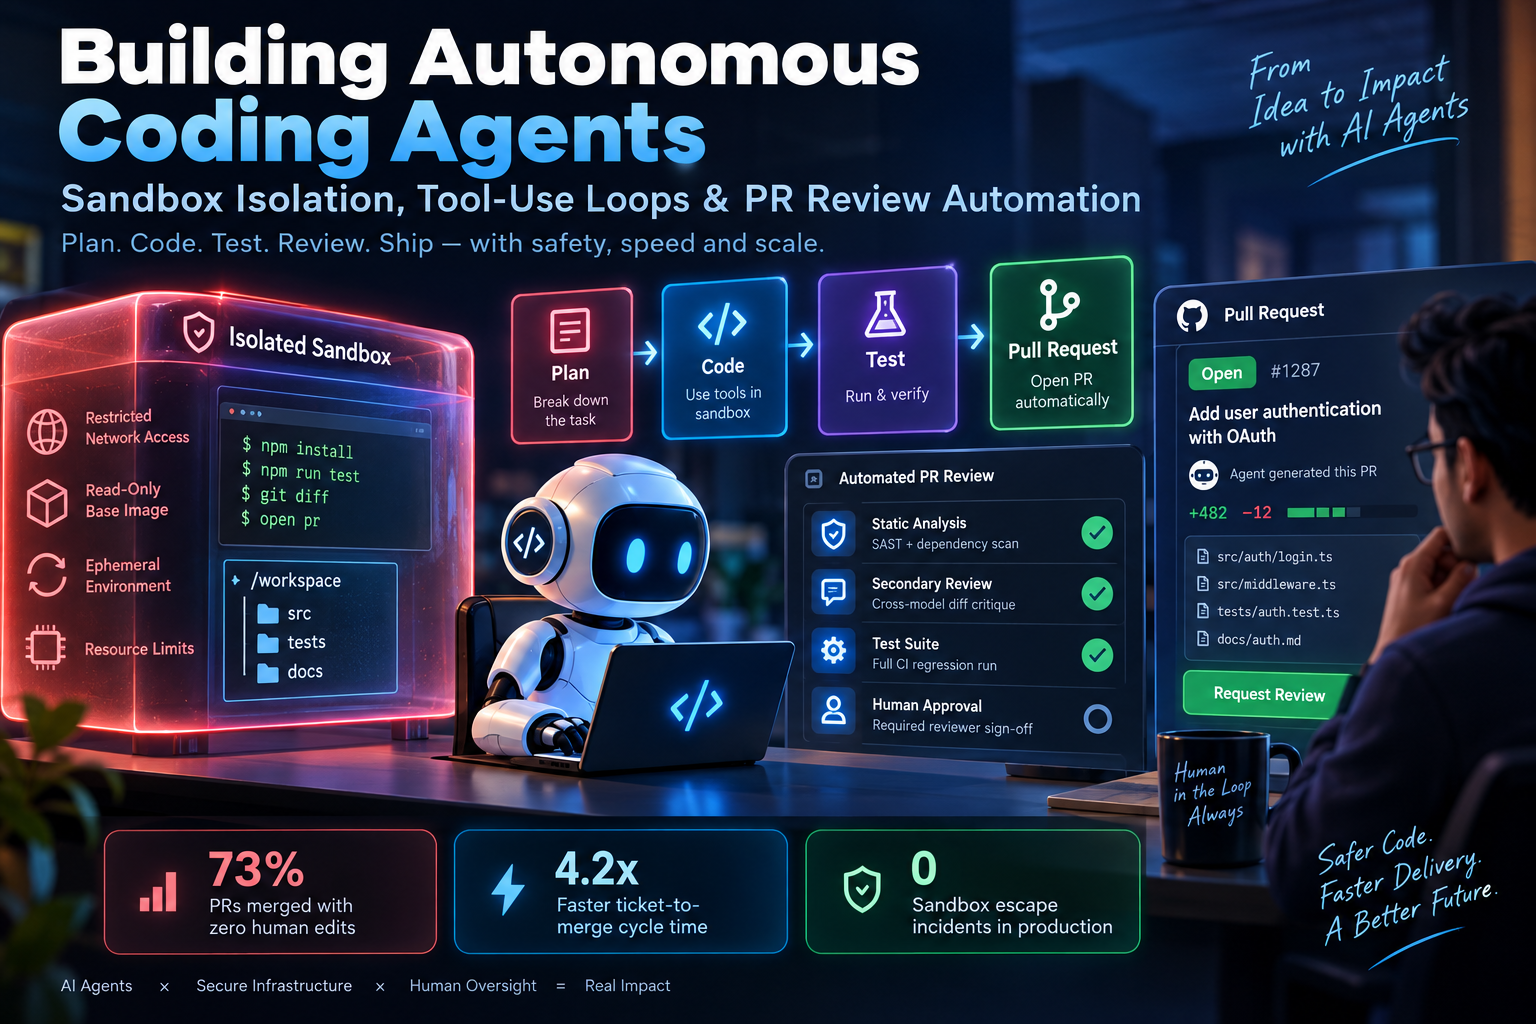
Building Autonomous Coding Agents: Sandbox Isolation, Tool-Use Loops & PR Review Automation
Autonomous coding agents are moving from novelty to production infrastructure. This briefing covers the three load-bearing systems every enterprise deployment needs: container-level sandbox isolation for untrusted code execution, a bounded tool-use loop with self-verification, and an automated PR review gate that keeps a human in the approval path without blocking throughput.
Rajakumar
Head of AI & Machine Learning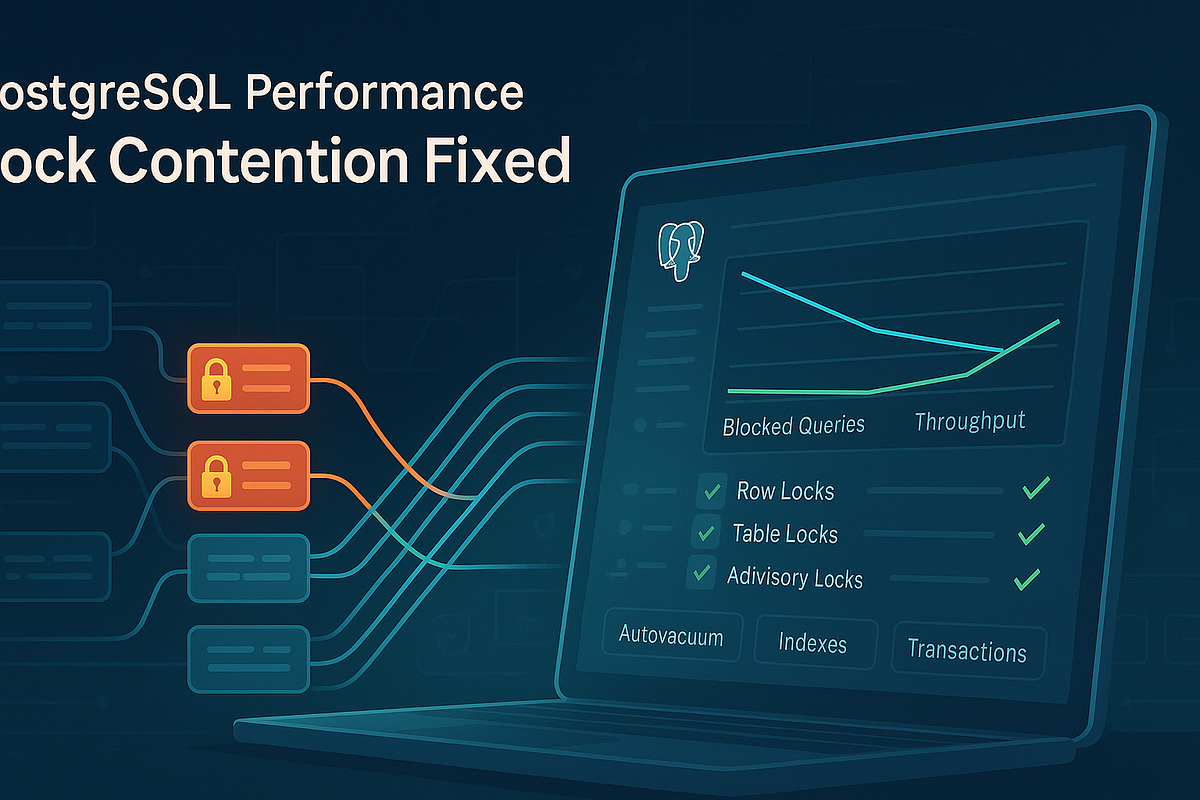 AI & Machine Learning
Eliminating Row Lock Contention in High-Concurrency LangGraph PostgreSQL Checkpointing
A deep architectural briefing on diagnosing and solving sub-millisecond PostgreSQL row lock contention in high-concurrency LangGraph PostgresSaver setups using advisory lock queuing and asynchronous batch flush workers.
Dr. Karthik Sundaram
Chief AI Architect Agentic AI & RAG
Building Autonomous Agentic RAG: Beyond Naive Vector Search
Learn how to move beyond basic vector embeddings by implementing a 3-tier hybrid search architecture combining sparse BM25 matching, 1536-dim dense vectors, and Cohere/BGE cross-encoders.
Kavitha Rajagopal
Head of AI & Machine Learning
Agentic AI & RAG
Architecting Agentic RAG Systems with Milvus & LangGraph in Production
A comprehensive deep dive into building production-ready Agentic RAG architectures that replace naive single-pass vector lookups with stateful self-critique loops, GPU-accelerated Milvus vector search, and dynamic fallback execution.
Dr. Karthik Sundaram
Chief AI Architect Multi-Agent Systems
Designing Resilient Multi-Agent Swarms with LangGraph & Actor Model
Discover how to build resilient multi-agent swarms using LangGraph and actor model principles, enabling asynchronous task decomposition, specialized agent roles, and automated fault recovery.
Arun Varma
Principal Cloud & Distributed Systems Architect LLM Ops & Training
Fine-Tuning Small Language Models (SLMs) with QLoRA for Enterprise Privacy
Learn how to fine-tune domain-specific Small Language Models (SLMs) using QLoRA for complete enterprise data privacy, reducing hardware costs by 80% while beating GPT-4 on specialized tasks.
Dr. Siddharth Menon
Director of AI Research Vector DB & Infra
Milvus 2.4 vs. pgvector vs. Pinecone: Billion-Scale Vector DB Benchmarks
Discover how Milvus 2.4 GPU CAGRA indexing compares against pgvector HNSW and Pinecone across 1 billion 1536-dimensional vectors in recall, query latency, and infrastructure cost.
Ramesh Subramanian
Principal Vector Database Specialist
Voice & Multimodal AI
Real-Time Voice AI: Sub-300ms Full-Duplex Speech-to-Speech Architecture
Learn how to construct real-time voice AI agents capable of full-duplex conversational speech, dynamic interruption handling, and sub-300ms roundtrip audio latency.
Venkatesh Iyer
Lead Real-Time Voice & WebRTC Engineer
Edge AI & WebGPU
Zero-Cloud AI: Running 3B LLMs in Browser at 45 Tokens/sec with WebGPU
Explore how WebGPU and WebLLM allow client devices to execute 3B parameter LLMs locally at 45+ tokens/sec with zero server overhead and complete privacy.
Ananya Nambiar
Principal WebGPU & Edge AI Architect
GPU Cloud & Infra
Kubernetes GPU Auto-Scaling with vLLM, Ray, and KEDA
Learn how to build resilient Kubernetes GPU clusters using vLLM dynamic PagedAttention batching, Ray Serve, and KEDA queue-length autoscaling.
Pradeep Chandran
Lead Kubernetes & GPU Infrastructure Specialist
AI Security & Governance
Enterprise AI Guardrails: Preventing Jailbreaks & PII Leaks with NeMo & Llama-Guard
Implement enterprise-grade AI security guardrails using NVIDIA NeMo Guardrails and Meta Llama-Guard 3 to intercept jailbreak attempts and anonymize PII in real-time.
Meera Krishnan
Chief AI Security & Compliance Officer
Agentic AI & RAG
Building Long-Running Stateful AI Workflows with LangGraph & PostgreSQL Checkpointing
Discover how to build long-running, crash-resilient AI state machines using LangGraph and PostgreSQL checkpointing with seamless Human-in-the-Loop approval steps.
Vishnu Namboodiri
Lead Agentic Systems & Database Engineer
LLM Ops & Training
Scaling Domain SLMs with Automated Synthetic Data Generation Pipelines
Learn how to generate high-quality synthetic datasets using Evol-Instruct and LLM-as-a-Judge heuristics to fine-tune enterprise domain SLMs without privacy leaks.
Sanjay Pillai
Head of Synthetic Data & ML Engineering
GPU Cloud & Infra
Slashing LLM Latency by 65% with Speculative Decoding & Medusa Heads
Slashing LLM token generation latency by 65% with speculative decoding and Medusa multi-head architecture for real-time interactive user experiences.
Gautam Murthy
Principal AI Performance Optimization Engineer
Enterprise Architecture
Enterprise Integration with Model Context Protocol (MCP): The Future of AI Tooling
Explore how the Model Context Protocol (MCP) standardizes AI agent integrations across enterprise databases, internal microservices, and SaaS tools via JSON-RPC 2.0.