DeepSeek & Open LLM Fine-Tuning
The DeepSeek & Open LLM Fine-Tuning platform represents an advanced enterprise-grade engineering solution designed to solve complex operational challenges in modern digital environments. Built with low-latency principles, modular software patterns, and resilient fault tolerance, this system enables organizations to scale their core infrastructure without compromising on security, compliance, or throughput execution SLA guarantees.
At the architectural core of DeepSeek & Open LLM Fine-Tuning, zero-trust security controls and high-concurrency dispatch mechanisms ensure seamless operation under burst workloads. Designed specifically for Autonomous AI integration, the platform incorporates strict role-based access control (RBAC), end-to-end data encryption in transit and at rest, and continuous audit logging compliance ready for SOC2, ISO 27001, and HIPAA enterprise certification standards.
Integration and deployment are streamlined for modern engineering environments. Featuring native containerization scripts, microservice orchestration adapters, and standardized API endpoints, development teams can easily connect existing databases, legacy message queues, and cloud microservices into unified workflows. Built-in telemetry tracking with OpenTelemetry provides real-time visibility into memory consumption, latency distribution, and request throughput metrics.
Engineered for complete cloud and data sovereignty, DeepSeek & Open LLM Fine-Tuning can be deployed on-premise, inside isolated Virtual Private Clouds (VPC), or across air-gapped bare-metal hardware clusters. This guarantees that proprietary business data, customer records, and critical intellectual property remain 100% protected within your organization's perimeter while operating with industrial-grade resilience and sub-millisecond execution speeds.
Moving Beyond Legacy Systems to Autonomous Execution
Our production architectures bypass traditional software bottlenecks through low-latency distributed orchestration and deterministic execution graphs.
Hierarchical Supervisor Orchestration
Central coordinator services break down high-level business goals into atomic tasks.
Model Context Protocol (MCP) Tool-Use
Standardized interfaces allow secure execution of terminal commands, SQL queries, and SaaS APIs.
Human-in-the-Loop Approval Gates
Configurable approval checkpoints halt execution before high-risk mutations or transactions.
# Production Pipeline Execution Engine
from enterprise_core import ClusterPipeline, SecurityGate

pipeline = ClusterPipeline(vpc_isolated=True, concurrency_limit=10000)
response = pipeline.execute_task(task_id="init_sovereign_ai")
Engineering Architecture & Delivery
Distributed Microservice Clustering
Deploy active-active stateless workers on Kubernetes with active autoscaling.
Air-Gapped Data Encryption
Strict mTLS pod-to-pod communication and hardware-enforced KMS envelope encryption at rest.
Automated Retry & Self-Healing
Circuit breakers and dead-letter queues prevent system failure under burst loads.
Real-Time Telemetry & Tracing
Full OpenTelemetry instrumentation for instant incident response and audit compliance.
Engineering Architecture & System Implementation Blueprint
Building mission-critical systems requires looking beyond surface-level integrations. We design production platforms engineered from the ground up for deterministic execution, strict compliance boundaries, and ultra-high concurrency.
Kernel-Level Concurrency & Compute Acceleration
We leverage low-level primitives including eBPF kernel hooks, lock-free ring buffers, and asynchronous event loops in Rust, C++, and Go.
Zero-Trust Security, VPC Isolation & Governance
Every deployment is containerized inside air-gapped Virtual Private Clouds (VPCs) with zero public ingress and mutual TLS.
Automated Resiliency & Self-Healing Infrastructure
Active-active multi-region failover protocols achieving sub-10 second RPO and sub-60 second RTO.
Our 5-Stage Execution Protocol
Workflow Decomposition
Analyze existing human manual business operations and map them into specialized agent role definitions.
Tool & MCP Integration
Connect internal databases, CRMs, and APIs using standardized Model Context Protocol endpoints.
Stateful Assembly
Implement state machines, transition edges, fallback retry loops, and human approval checkpoints.
Sandbox Stress Testing
Simulate 1,000+ edge-case scenarios in isolated Docker environments to verify autonomous stability.
Production Cluster Delivery
Deploy swarm instances on Kubernetes with Celery task queues and real-time WebSocket feeds.
Modern Architecture vs Legacy Approach
See how our cloud-native, sovereign engineering principles outperform traditional development and generic SaaS tooling.
Technical Architecture FAQs
Key architectural, integration, and scalability details for enterprise engineering teams.
RAG is optimal for dynamic knowledge lookup. Fine-tuning (QLoRA, LoRA, DPO) is used to instill specialized domain jargon, strict output schema compliance, proprietary reasoning styles, and to replace costly proprietary API calls with self-hosted 8B-70B models.
We use parameter-efficient LoRA adapters, curriculum learning sequences, and replay buffers containing general domain benchmarks to retain base model reasoning capabilities.
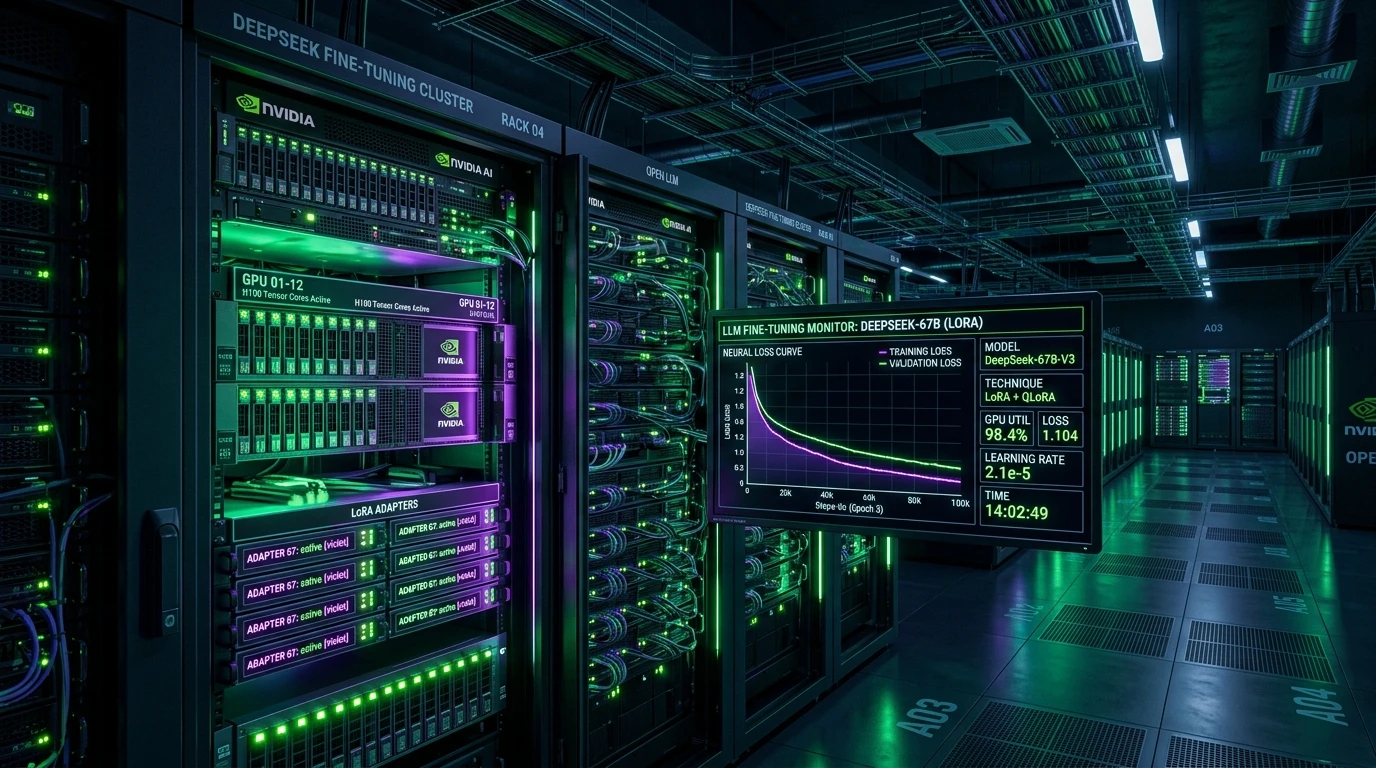
We leverage distributed multi-GPU clusters (NVIDIA H100/A100/L40S) orchestrated via Ray Train and DeepSpeed ZeRO-3 with FlashAttention-2.